From the source
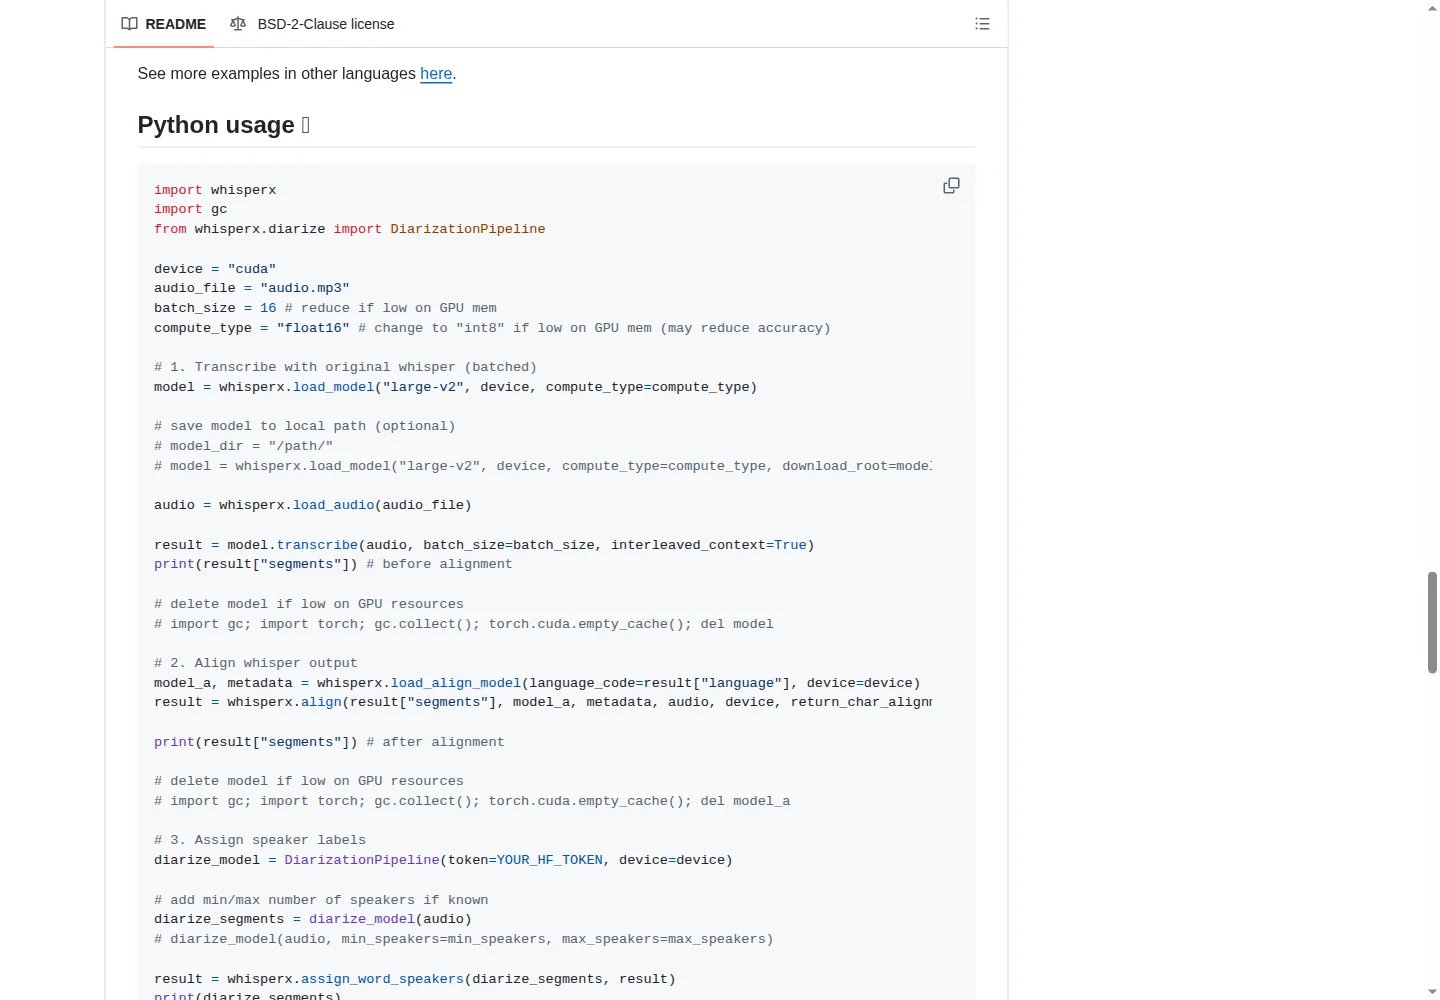
How it works
- The documented sequence transcribes audio, uses a language-specific alignment model, then assigns estimated speaker labels. Public source access does not provide model permissions or suitable hardware.
- Words outside the alignment dictionary, including some numbers and currencies, can lack times. An untimed word does not establish absent speech.
- The README says overlapping speech is handled poorly and diarization is imperfect. Speaker labels do not establish a person's identity.
- The diarization implementation assigns labels through timing overlap. Its source was read, not tested on recordings. Headline throughput and sponsored API claims are not local accuracy results.
- Review names, numbers, overlap, readability and attribution before publishing subtitles. No accuracy, correction-time or savings result was measured.
Workflow guide
Approve a pinned, reviewed WhisperX environment before installation. Select CPU or supported GPU settings for a consented sample with known language and reviewed speaker references.
Transcribe audio with documented batch and model settings.
Run a suitable language-specific alignment model to estimate word times from the transcript and audio.
Accept required model terms and protect the Hugging Face read token before enabling diarization to assign estimated speaker labels to aligned words.
Prepare captions from reviewed timings and labels. Check overlap, names, numbers, untimed words and readability before human approval of publication or identity attribution.
Record timing errors, untimed-word rate, speaker-label accuracy, readable coverage and correction time for the fixed labeled sample.